While not a hard and fast law of nature, it is a general rule of thumb that plots look better when made using R's ggplot2 library than they do coming straight out of Excel, Matlab, Python, or even the native R plotting routines. While there is a small learning curve associated with ggplot2, the results are well worth the effort. This post is intended to get you through that learning curve ... fast.
First, an introduction:
ggplot2 is a package associated with the R programming language. The "gg" in "ggplot" refers to the "
grammar of graphics" approach to plotting. You don't need to know many specifics about this. Just think of a plot as a series of layers, and all you do is add/manipulate layers to make a finished product. The primary advantage is the enormous flexibility this package provides.
First things first, the
documentation for ggplot2 is quite good. Familiarize yourself with it, as it will be your best friend, with
Stack Overflow coming up as a close second.
And now for a quick tutorial, to get you through that learning curve. The data, code and resulting images can be downloaded from the
blog's bitbucket repository (the files can be found under "downloads" or in the "source" in the folder "ggplot_intro").
I've chosen the
dow jones index data set from the UCI Machine Learning Repository. The data is straight forward. The value of several stocks is tracked on a weekly basis over the course of a few months. The ggplot2 functions take data in "long format". This data set just happens to already be in long format, which you can see in the following image.
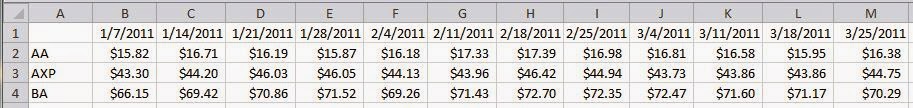
"Long format" refers to the way the time series for each individual stock are separate. This is easier to understand when contrasted with the "wide format". An example of the "wide format" could have the rows indicate the stock ID, the columns represent the date, and the fields populated with the relevant data (see the following image):
As you can see, the long format can fit much more information into the same structure (where the wide format would require several tables to express the same information). However, the wide format displays the data more efficiently. The main point here is that ggplot2 requires long format, so it's good to be able to recognize it.
The long format data needs to be stored in an R data frame. If you're unfamiliar with R or data.frames, now may be a good time to do a quick internet search, but the gist of a data frame is that it can store information in a matrix format, but each column can be a different data type (integer, string, etc.). This comes in handy while plotting.
Now for some R code, which we'll go through in detail:
 # Plot dow jones index dataset (https://archive.ics.uci.edu/ml/datasets/Dow+Jones+Index)

 library(ggplot2)

 # Load data set
 d = read.table('dow_jones_index.data', sep=',', header=T)

 # Note: This particular data set is already in "long" format

 # Convert to appropriate data types
 d$date = as.Date(d$date,'%m/%d/%Y')
 d$open = as.numeric(gsub("[,$]", "", as.character(d$open)))

 # Simple plot with point and line layers
 p1 = ggplot(d, aes(x=date, y=open, g=stock )) +
   geom_point() +
   geom_line()
 print(p1)

 ggsave(file="dow_jones_index_p1.jpg", plot=p1, width=300, height=210, units="mm")
Let's look at the code line by line:
The "library(ggplot2)" imports the ggplot2 functions and makes them available to you.
The "read.table()" command reads in the comma-delimited data file and, conveniently, converts it into a data frame. Because the data is already in long format, there is no need to change the data organization. When using ggplot2, it is often necessary to reformat into long. For this purpose, you can do it manually, or you can use something like the reshape2 package for R.
The "as.Date()" and "as.numeric()" functions convert the string-type variables into the correct R data types, and re-save them to the data frame "d".
Once these few steps are accomplished, you're ready to plot.
First, notice that the ggplot object is saved to the variable "p1". Next, notice that several layers are appended to the ggplot object using the plus "+" sign. The purpose of the original ggplot() call is to pass in the data set (in this case, "d"), and indicate the columns inside of "d" that will be assigned to the x-axis, y-axis, and "group". In this case, the x-axis will refer to the date, the y-axis will refer to the opening value of the stock for that date, and g or "group" indicates which data points belong together (which in this case are the different stocks).
We add data points by appending "geom_point()". We add lines connecting those points using "geom_line()".
"print(p1)" displays the graph. "ggsave()" saves the graph to a file.
We make this graph more interesting and understandable by adding layers, and modifying layers:
 # Plot with lines colored by stock, larger points and fonts, and axis labels
 p2 = ggplot(d, aes(x=date, y=open, g=stock )) +
  geom_line(size=1.1, aes(color=stock)) +
  geom_point(alpha=0.5, size=4) +
  theme_bw() +
  xlab("Date (2011)") +
  ylab("Opening Price ($)") +
  title("Dow Jones Index 2011") +
  theme(text = element_text(size=20))
 print(p2)
 ggsave(file="dow_jones_index_p2.jpg", plot=p2, width=300, height=210, units="mm")
Notice that "geom_line()" is moved to be before "geom_point()". This draws the points after the lines. The lines are modified to associate color with the stock groupings. The size and opacity of lines and points are modified using "size" and "alpha" attributes. "theme_bw()" modifies the background to be white instead of grey. The "theme()" element does lots of things, and in this case it changes the text size on the axes.
And there you go, you've made a beautiful plot using R ggplot2! There is a lot that can be done, and future posts will discuss those possibilities. The customizability of ggplot2 extends to literally anything you want to draw, including
overlaying spatial data on maps. It's all about
the layers.